

The rapid ascent of Artificial Intelligence (AI) has been met with a mixture of awe and apprehension. While the transformative potential of AI is undeniable, the very companies pioneering this technology have, in the eyes of many Americans, squandered the goodwill of the public. This alienation stems from a perceived imposition of costs—both financial and societal—without adequate consideration for consent or community impact. As local opposition to the burgeoning AI infrastructure, particularly data centers, gains momentum across the United States, the incoming Congress faces a critical juncture: the opportunity to enact meaningful regulation and establish accountability for an industry that has, thus far, largely operated with a sense of unchecked autonomy.
The core of the public’s discontent lies in the dual challenges presented by AI development. Firstly, the economic burden of AI is increasingly being shifted onto consumers and communities. This manifests in several ways, from the subscription models required to access advanced AI tools to the significant environmental and infrastructural demands placed upon localities to support the massive data centers that power these technologies. These facilities, essential for training and running AI models, consume vast amounts of energy and water, and require substantial land use, often leading to concerns about local resource depletion, increased utility costs for residents, and the displacement of other development.
Secondly, the issue of consent has become a flashpoint. AI systems, particularly those that learn from vast datasets, often utilize information that individuals may not have explicitly agreed to share for AI training purposes. The "make something people want" ethos, once a guiding principle for startups, seems to have been overshadowed by a less transparent approach where the products are built using data that the public may not want used in that specific manner. This raises profound questions about data privacy, intellectual property rights, and the ethical boundaries of data harvesting in the age of advanced AI.
The visible impact of these concerns is the growing resistance to the construction of new data centers. In numerous communities across the United States, residents, environmental groups, and local officials are voicing strong opposition to proposed data center projects. These objections are not merely NIMBYism (Not In My Backyard); they represent a legitimate outcry against perceived unchecked corporate power and a demand for greater transparency and community benefit. The rejection of these projects by voters and local authorities signals a clear message: the unchecked expansion of AI infrastructure, without addressing its externalities, is no longer acceptable.
The Shifting Landscape of AI Development and Public Perception
The narrative surrounding AI has evolved significantly. Initially, there was widespread optimism about AI’s potential to solve complex problems, boost productivity, and improve various aspects of life. Companies like OpenAI, with figures like Sam Altman at its helm, were seen as at the forefront of this revolution, promising a future shaped by intelligent machines. Altman’s own past advocacy for building products that "people want," a philosophy he espoused during his tenure at the startup incubator Y Combinator, set a high bar for ethical and user-centric development. However, the current trajectory of AI development, as perceived by many, appears to deviate from this foundational principle.
The development of large language models (LLMs) and other advanced AI systems has required an unprecedented scale of computational power. This, in turn, has driven the demand for massive data centers. These facilities are not akin to traditional server farms; they are colossal structures requiring dedicated power grids, extensive cooling systems that consume significant water resources, and land parcels that can be several acres in size. The environmental footprint of these operations is substantial, leading to concerns about carbon emissions from energy consumption and the strain on local water supplies, especially in regions already facing water scarcity.
A Growing Tide of Local Opposition: Data Centers Under Scrutiny
The backlash against data centers is not an isolated phenomenon but a growing national trend. Communities are increasingly scrutinizing proposals for these facilities, armed with newfound awareness of their potential impacts.
- Oregon: In the Umatilla region of Oregon, residents have expressed concerns about the energy and water demands of proposed data centers, highlighting the strain on local resources.
- Virginia: Northern Virginia, a major hub for data centers, has seen increasing local resistance, with debates focusing on the environmental impact, increased traffic, and the allocation of limited energy resources.
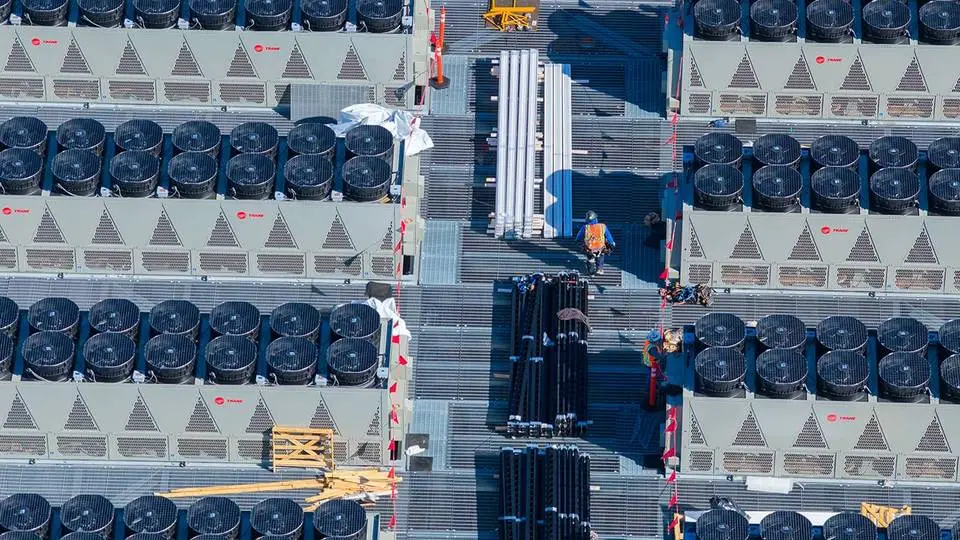
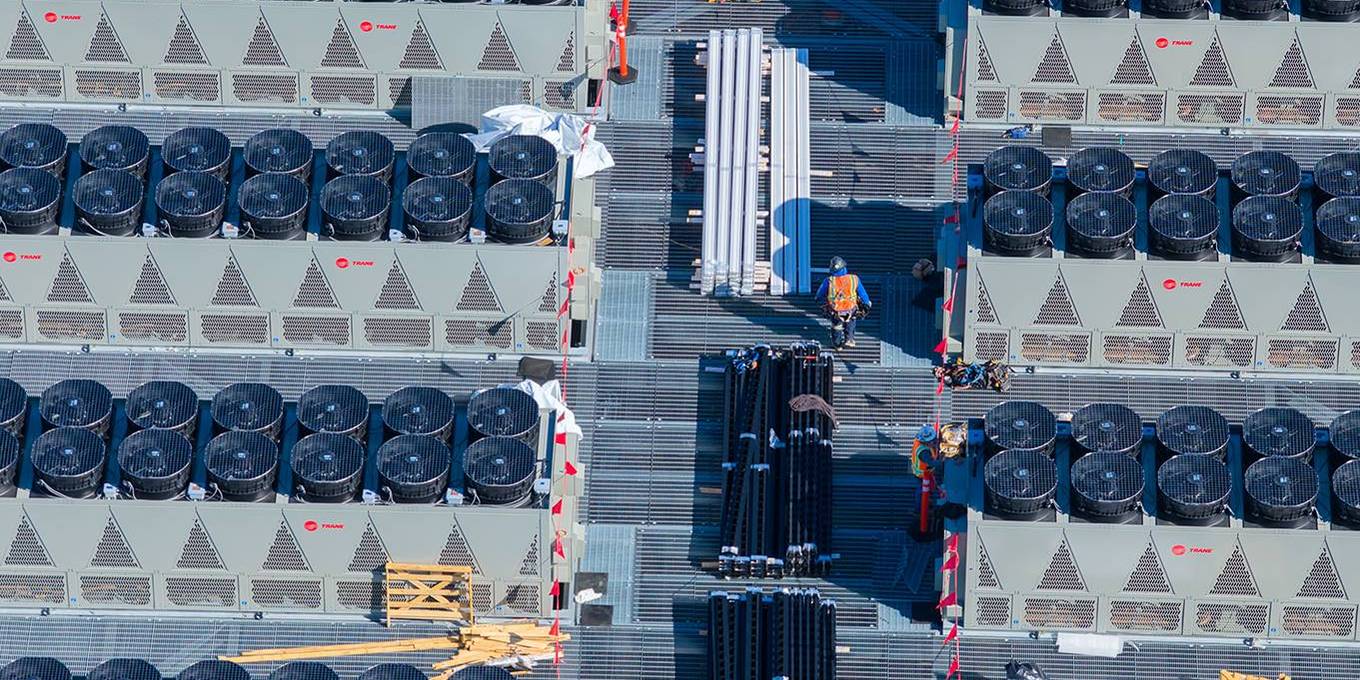
- California: In Vernon, California, as depicted in the accompanying imagery, the construction of large data centers has become a visible symbol of this industrial expansion, prompting discussions about community planning and sustainability. Local governments are grappling with balancing economic development opportunities with the environmental and social costs.
- New York: In upstate New York, communities have similarly pushed back against data center projects, citing concerns over energy consumption and the potential impact on local ecosystems.
This widespread opposition is not being driven by a single issue but by a confluence of factors: environmental degradation, strain on public services, and a feeling of being marginalized in the decision-making process. The perception is that these projects are often imposed upon communities with little regard for their existing infrastructure, environmental carrying capacity, or the long-term well-being of residents.
The Consent Conundrum: Data and AI Training
A significant ethical quagmire surrounding AI development is the question of data consent. The training of advanced AI models, particularly LLMs, relies on the ingestion of massive datasets, often scraped from the internet. This data includes text, images, and other forms of content created by individuals, artists, writers, and businesses. The crux of the issue is whether the creators of this content have implicitly or explicitly consented to its use for training AI models that may ultimately compete with them or profit from their original creations.
- Intellectual Property Rights: Artists and writers have raised alarms about their work being used without permission to train AI models that can then generate similar content, potentially devaluing their original creations and livelihoods. Legal challenges are emerging, exploring the boundaries of copyright law in the context of AI training data.
- Privacy Concerns: Personal information, even if publicly available, may not have been intended for AI training. The aggregation and analysis of such data by AI systems can lead to new forms of profiling and surveillance, raising significant privacy concerns for individuals.
- Lack of Transparency: The opaque nature of AI training data selection and curation makes it difficult for individuals and creators to understand how their data is being used, or to opt out if they choose. This lack of transparency fuels public distrust.
The Opportunity for Congressional Action
The growing public dissent and the visible rejection of data center projects by voters present a clear mandate for the incoming Congress. This is not just an opportunity but a necessity to establish a regulatory framework that can guide the responsible development and deployment of AI.
Key Areas for Legislative Intervention:
-
Data Privacy and Consent Reform:
- Strengthened Consent Mechanisms: Legislation should mandate clear, affirmative consent for the use of personal data in AI training. This could involve opt-in requirements rather than opt-out.
- Data Usage Transparency: Companies should be required to disclose the sources and types of data used for training their AI models, allowing for greater public scrutiny.
- Data Portability and Deletion Rights: Individuals should have the right to access, port, and request the deletion of their data from AI training sets where feasible, mirroring existing privacy regulations like GDPR.
-
Environmental and Infrastructure Regulation for Data Centers:
- Energy Efficiency Standards: Mandate stringent energy efficiency standards for data centers, encouraging the use of renewable energy sources and advanced cooling technologies that minimize water consumption.
- Environmental Impact Assessments: Require comprehensive environmental impact assessments for all new data center projects, with meaningful community input and opportunities for mitigation.
- Resource Management Plans: Implement regulations that ensure data centers do not place undue strain on local water and energy resources, particularly in drought-prone or energy-constrained regions.
-
Accountability and Liability Frameworks:
- Defining AI Liability: Establish clear legal frameworks for determining liability when AI systems cause harm, whether through bias, misinformation, or other detrimental outcomes.
- Industry Standards and Audits: Encourage or mandate industry-wide standards for AI safety, fairness, and transparency, with provisions for independent audits.
- Consumer Protection: Enact legislation to protect consumers from predatory AI practices, such as deceptive marketing or exploitative pricing models.
Broader Impact and Implications
The current standoff between AI companies and the American public has significant implications for the future of technology and society.
- Innovation vs. Regulation: The challenge for policymakers will be to strike a balance between fostering innovation and protecting public interests. Overly burdensome regulations could stifle technological advancement, while a lack of oversight risks unchecked corporate power and negative societal consequences.
- Public Trust: Rebuilding public trust in AI is paramount. Transparency, accountability, and a genuine commitment to addressing community concerns are essential for AI to be embraced as a beneficial force.
- Global Competition: The United States’ approach to AI regulation will have global ramifications. Establishing a responsible framework could set a precedent for other nations, influencing the international development of AI.
- Economic Disparities: Without careful planning, the benefits of AI could disproportionately accrue to a few, while the costs are borne by many. Congressional action can help ensure a more equitable distribution of AI’s advantages.
The growing resistance to data centers and the broader public outcry against AI companies’ practices are not signs of technophobia, but rather a call for a more responsible, ethical, and equitable approach to technological advancement. The incoming Congress has a unique opportunity to address these concerns, transforming the current friction into a foundation for a future where AI serves humanity, rather than overwhelming it. The era of unchecked AI expansion is, by all indications, coming to an end, and the legislative agenda now holds the key to shaping what comes next.
